Scientists release new ‘four as’ framework to tackle key ethical challenges governing AI
Anglia Ruskin researchers argue the AI governance debate collapses four separate problems into one, and propose sorting them by who can enforce a fix.
 Edited By: Joseph Shavit

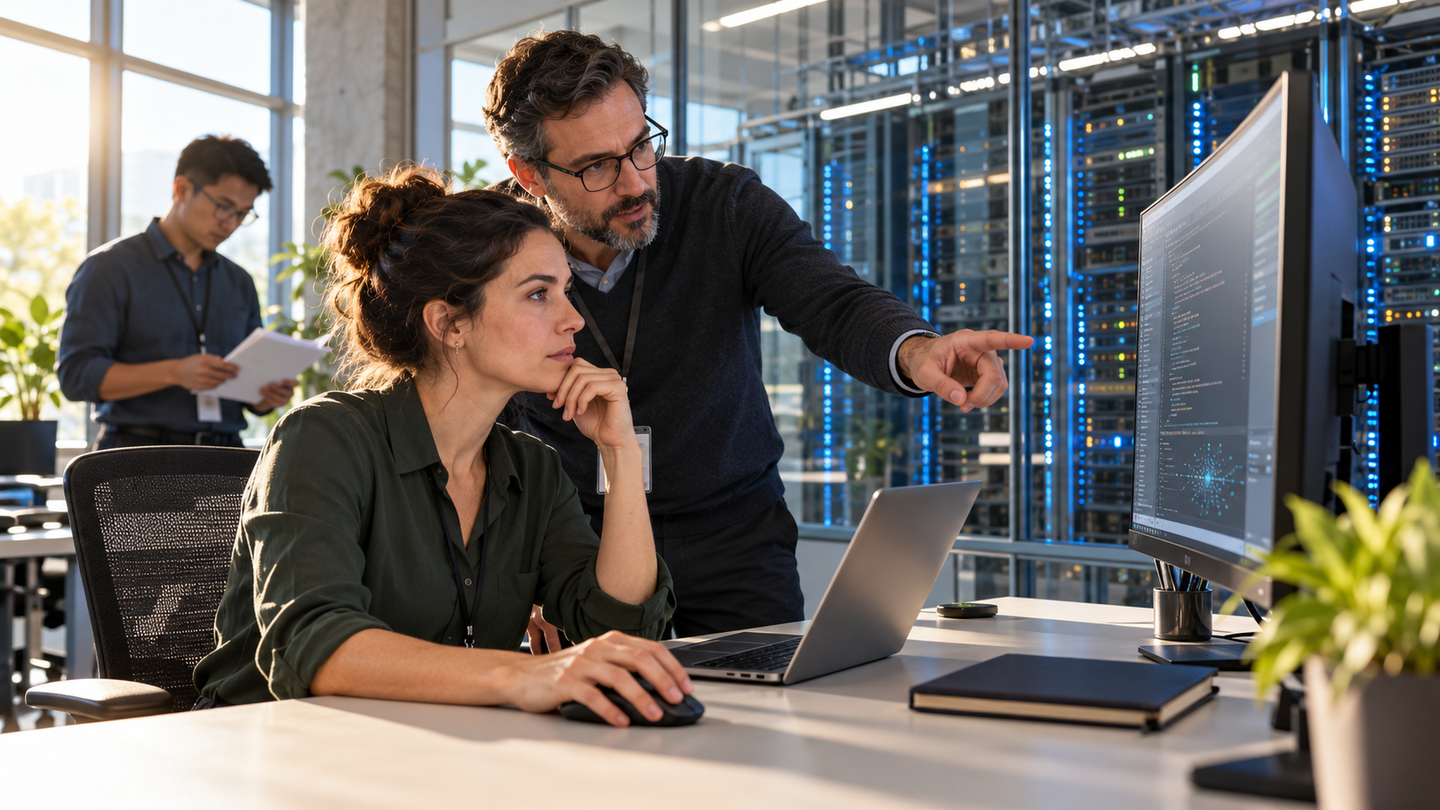
Illustrative scene of a team reviewing an AI system beside server infrastructure. The proposed Four As framework addresses human control, access, decision-making authority and the distribution of AI’s benefits and burdens. (CREDIT: The Brighter Side of News)
- Two computer scientists argue that "slow down AI" is the wrong unit of debate, and propose sorting every governance question into four distinct problems: Action, Access, Authority and Allocation.
- The framework assigns each problem to whoever can actually enforce it, with developers handling control, regulators handling access, deploying institutions handling delegated decisions, and governments handling distribution.
- It also predicts that fixing one problem can create another, since restricting access to a powerful model reduces misuse while concentrating power in fewer hands.
Restricting who can use a powerful AI model makes misuse harder and concentrates power at the same time. Two researchers at Anglia Ruskin University in Cambridge treat that trade-off not as an awkward side effect but as the central insight of how AI should be governed. Their argument is that most governance debate collapses four separate ethical problems into one.
Kirti Prakash and Ian van der Linde of the university's Advanced Computing Research Centre call their proposal the "Four As." The categories are Action, Access, Authority and Allocation, and each names a different question about what society is prepared to permit.
The framework appears in the journal AI and Ethics. It is a conceptual proposal rather than an experiment, built from the ethics literature and from earlier attempts to govern powerful technologies.
Their starting claim is that the familiar framing has run out of usefulness. "The debate around frontier AI is often framed as a choice between accelerating development and slowing it down," Prakash said. "We argue that this is too blunt."
Four questions instead of one
Action asks whether humans retain effective control over what an AI system does. The concern survives even when the operators are authorised and well intentioned, because the question is about capability to intervene rather than good faith.
Access asks who should be allowed to obtain or use a capability that could cause serious harm. This problem can arise when a system is working exactly as designed, and the authors note that other fields already handle it through security clearances, licensing and export controls.
Authority asks something different again: not who may use a system, but which judgements may be handed to it. A model could be reliable and properly restricted and still raise an ethical problem if it effectively decides a clinical treatment or a military escalation without meaningful human review.
Allocation asks how benefits, burdens and power end up distributed. Individual deployments may each be defensible while their accumulation concentrates economic power, or imposes costs on people with no say.
The authors argue these four are genuinely separate using what they call an independence test. If you fully solved one, would the others disappear? Controlling a system does not settle who may access it, and legitimate access does not settle what decisions it may make.
Why a slowdown is an incomplete answer
The researchers call a global slowdown an incomplete objective rather than a wrong one. A laboratory can pause a training run or tighten evaluations, and that may address some control and access concerns while leaving delegated authority and distribution untouched.
Capability has also stopped being confined to single organisations. Existing models can be copied and adapted, open-weight systems cross borders, and meaningful gains now come from better inference, memory, tool use and agent coordination rather than from training a new frontier model.
Politics pulls against coordination too. The paper notes that Sam Altman, Elon Musk and Demis Hassabis have backed stronger pacing or oversight, while President Donald Trump rejected a substantial slowdown to keep the United States ahead of China, and China has objected to proposals it reads as constraints on its development.
Commercial incentives complicate restraint in a subtler way. Safety requirements that raise the cost of frontier work may favour firms that already hold the most compute and capital, and describing systems as exceptionally powerful can reinforce their perceived commercial value.
The authors are careful about what that does and does not prove. Neither dynamic shows that safety concerns are insincere, they write, and commercial interest does not invalidate genuine risk. The point is narrower: precaution itself redistributes power, so governance has to ask who gains authority as a result.
When fixing one problem creates another
Two failure modes follow from treating AI risk as one category. The first is governance mismatch, where an intervention addresses a different problem from the one at issue. Human oversight can strengthen accountability without touching the question of who should hold a dangerous capability.
Oversight that exists only on paper is the sharper version of that failure. The authors argue that procedural review can manufacture the appearance of accountability while leaving no actual ability to change what a system does.
Their worked example is a frontier cyber agent that passes containment testing and can be reliably interrupted. A narrow safety check might call the control problem solved, yet misuse potential keeps the access question open, and an ability to act on critical infrastructure raises the authority question too.
The second failure mode is what they call cross-locus displacement. Reducing concern in one category can intensify it in another, which is why the access restriction that lowers misuse risk can simultaneously create a concentration problem.
That logic produces their most pointed example. The authors read the White House Accord on Super Intelligence, with its layered internal monitoring, internal oversight, external evaluation and board supervision, as weighted almost entirely toward Action, leaving access, delegated authority and distribution unaddressed.
What history suggests
The precedents the authors draw on are deliberately imperfect analogies. Nuclear governance, recombinant DNA and gene editing are not equivalent to AI, but each forced a society to decide when technical capability creates obligations toward people who did not choose the risk.
Asilomar in 1975 is their central case. Scientists meeting on recombinant DNA did not call for abandoning the research, the authors note, but matched containment to risk, postponed experiments judged too dangerous for existing safeguards, and revised the rules as evidence accumulated.
Nuclear arms control supplies a different lesson about cooperation between rivals. It did not require complete trust, only the identification of outcomes neither side wanted, channels for communicating about dangerous incidents, and reciprocal constraints that left competition intact.
From these the authors propose what they call an AI stability framework rather than a moratorium. Its purpose would be a minimum ethical floor: constraints specific to each category, identifiable enforcers, common evaluation standards, signals that a safeguard has failed and scheduled reassessment.
What the framework does not settle
The Four As is a way of organising questions, not a body of findings. Nothing in it establishes how dangerous any particular system is, and the authors state plainly that the categories identify where an obligation arises rather than ranking risks by severity or probability.
The framework is also explicitly not a complete inventory of AI harms. The authors present the four categories as analytically separable but overlapping, acknowledging that a single system can engage all of them and that resolving one does not resolve the rest.
Nothing has been tested in operation. There is no case study of an institution adopting the approach, no measurement of whether it improves decisions, and the mapping of recent events onto the categories is described by the authors as qualitative.
The contemporary examples it leans on are also unsettled. A claimed proof of a long-standing mathematics problem is still going through evaluation, and simulated war games showing frequent nuclear signalling by current models are described in the paper itself as not demonstrating that AI would choose nuclear war.
One concrete test is already visible. Van der Linde points to the newly announced UK AI Biosecurity Lab, which will use frontier models supplied by companies including OpenAI, Anthropic and Google DeepMind, as a case where governance turns not on whether a capability exists but on who can reach it.
Dig deeper into AI governance
These resources cover the frameworks, risk taxonomies and historical precedents the study draws on.
The AI risk repository: A meta-review, database, and taxonomy of risks from artificial intelligence
A synthesis of more than a thousand catalogued AI risks, useful for seeing how differently other groups sort the same problems. (arXiv, August 2024)
Asilomar Conference (1975)
An account of the recombinant DNA meeting the authors treat as their central precedent for proportionate restraint. (Embryo Project Encyclopedia, Arizona State University, July 2024)
AI Risk Management Framework
The US standards body's approach to organising AI risk work, one of the existing frameworks this proposal positions itself against. (National Institute of Standards and Technology, January 2023)
Human genome editing: a framework for governance
Shows how another field built governance around applications carrying severe or irreversible consequences. (World Health Organization, July 2021)
Artificial Intelligence: the global landscape of ethics guidelines
The preprint of a widely cited survey finding broad agreement on AI principles alongside wide disagreement about applying them. (arXiv, June 2019)
Research findings are available online in the journal AI and Ethics.
The original story "Scientists release new 'four as' framework to tackle key ethical challenges governing AI" is published in The Brighter Side of News.
Related Stories
- Can AI detect when a person is lying — should we trust it?
- Half of surveyed UK novelists fear AI could replace their work entirely
- Can AI solve a Millennium Prize problem? OpenAI says its system just did
Like these kind of feel good stories? Get The Brighter Side of News' newsletter.
Shy Cohen
Writer